感谢 Sidrune AI 赞助本项目!一个入口,接入并管理全球主流 AI 模型。Sidrune AI 面向个人开发者、技术团队与企业,通过统一 API 接入并管理全球主流 AI 模型,多线路动态调度提升可用性,模型表现、响应时间与费用透明可查。根据不同模型与线路,API 调用成本较官方或基准价格可降低 40%~98%。通过专属链接注册,即可获得 $3 API 额度。
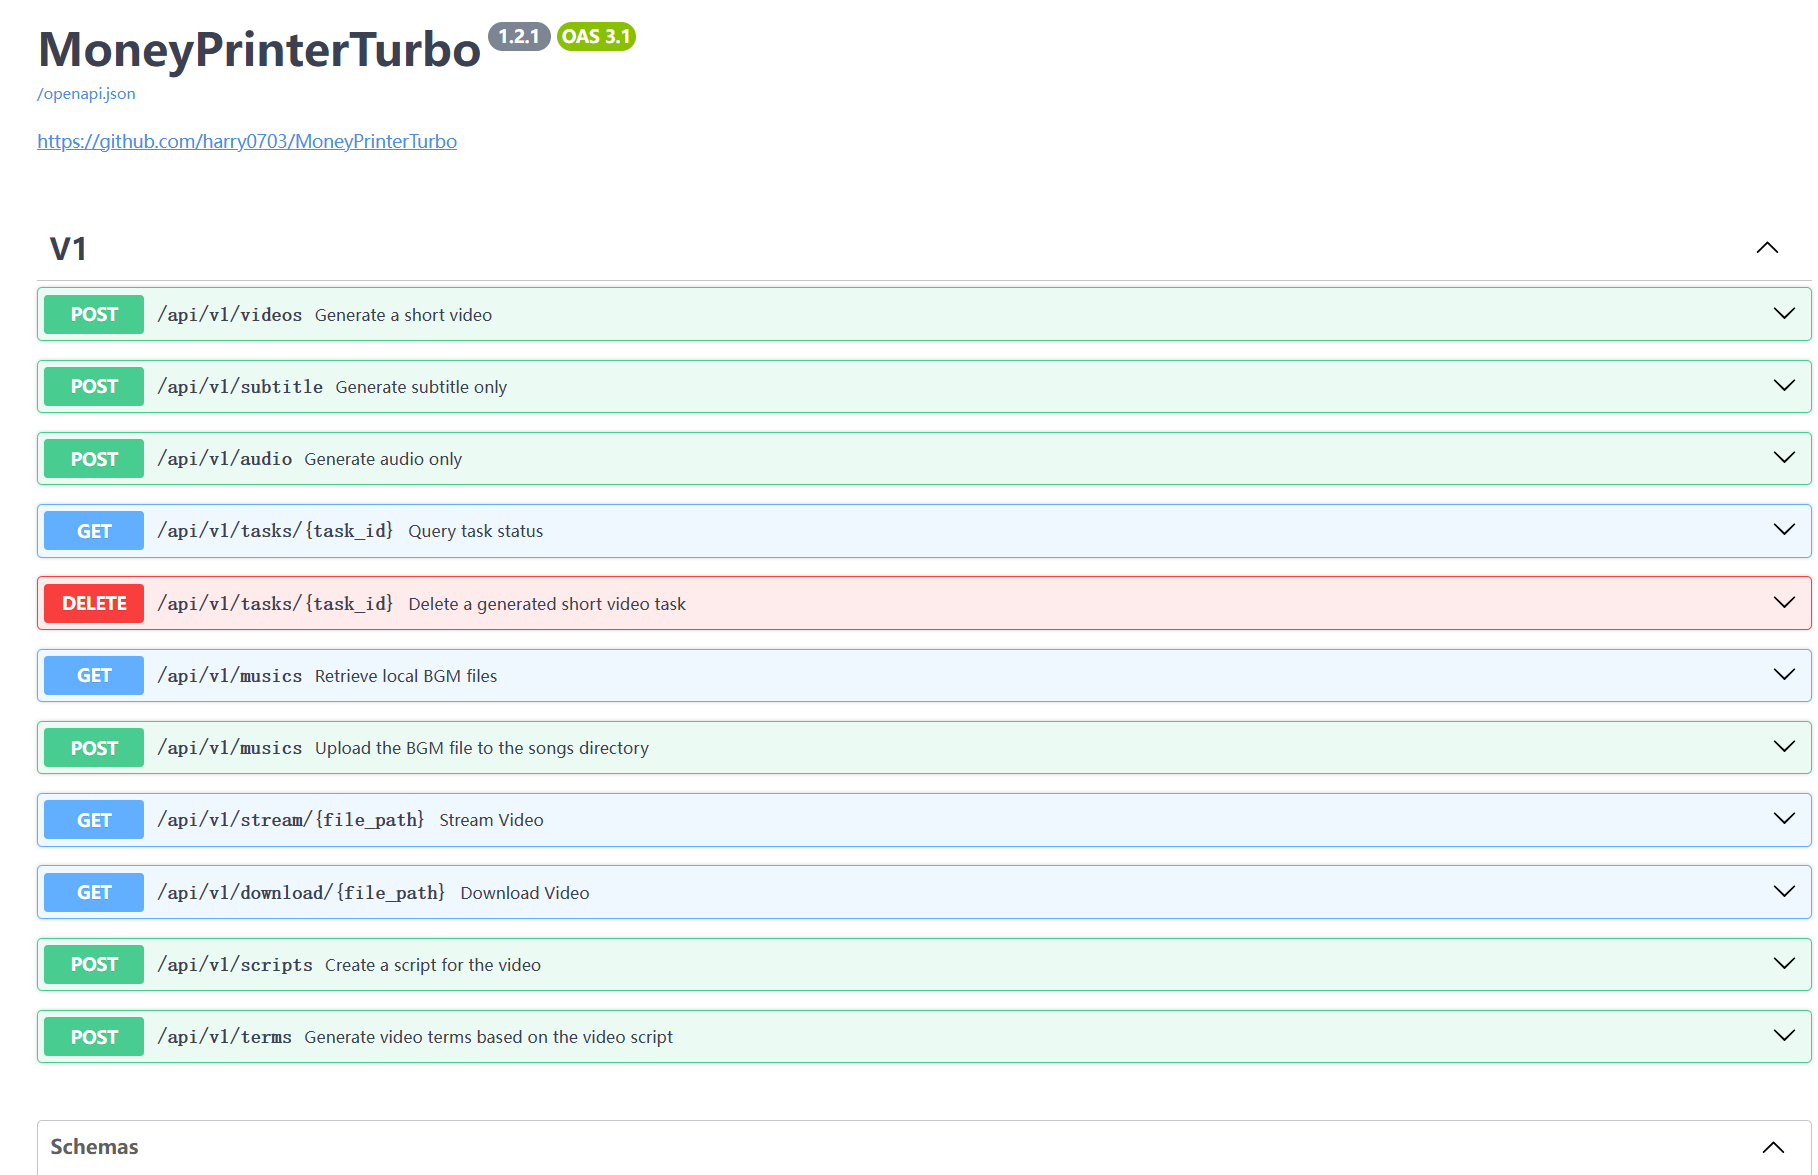
API 默认仅允许同源网页访问。只有独立网页前端需要从其他来源直接调用 API 时,才应通过环境变量 CORS_ALLOWED_ORIGINS 配置可信来源,例如 http://localhost:3000,https://frontend.example.com。curl、Postman、n8n 和其他服务端调用不受 CORS 限制。
[app]
# 请根据你的实际路径设置,注意 Windows 路径分隔符为 \\
ffmpeg_path = "C:\\Users\\harry\\Downloads\\ffmpeg.exe"
OSError: [Errno 24] Too many open files
这个问题是由于系统打开文件数限制导致的,可以通过修改系统的文件打开数限制来解决。
查看当前限制
ulimit -n
如果过低,可以调高一些,比如
ulimit -n 10240
Whisper 模型下载失败
LocalEntryNotFoundError: Cannot find an appropriate cached snapshot folder for the specified revision on the local disk and
outgoing traffic has been disabled.
To enable repo look-ups and downloads online, pass 'local_files_only=False' as input.
或者
An error occurred while synchronizing the model Systran/faster-whisper-large-v3 from the Hugging Face Hub:
An error happened while trying to locate the files on the Hub and we cannot find the appropriate snapshot folder for the
specified revision on the local disk. Please check your internet connection and try again.
Trying to load the model directly from the local cache, if it exists.
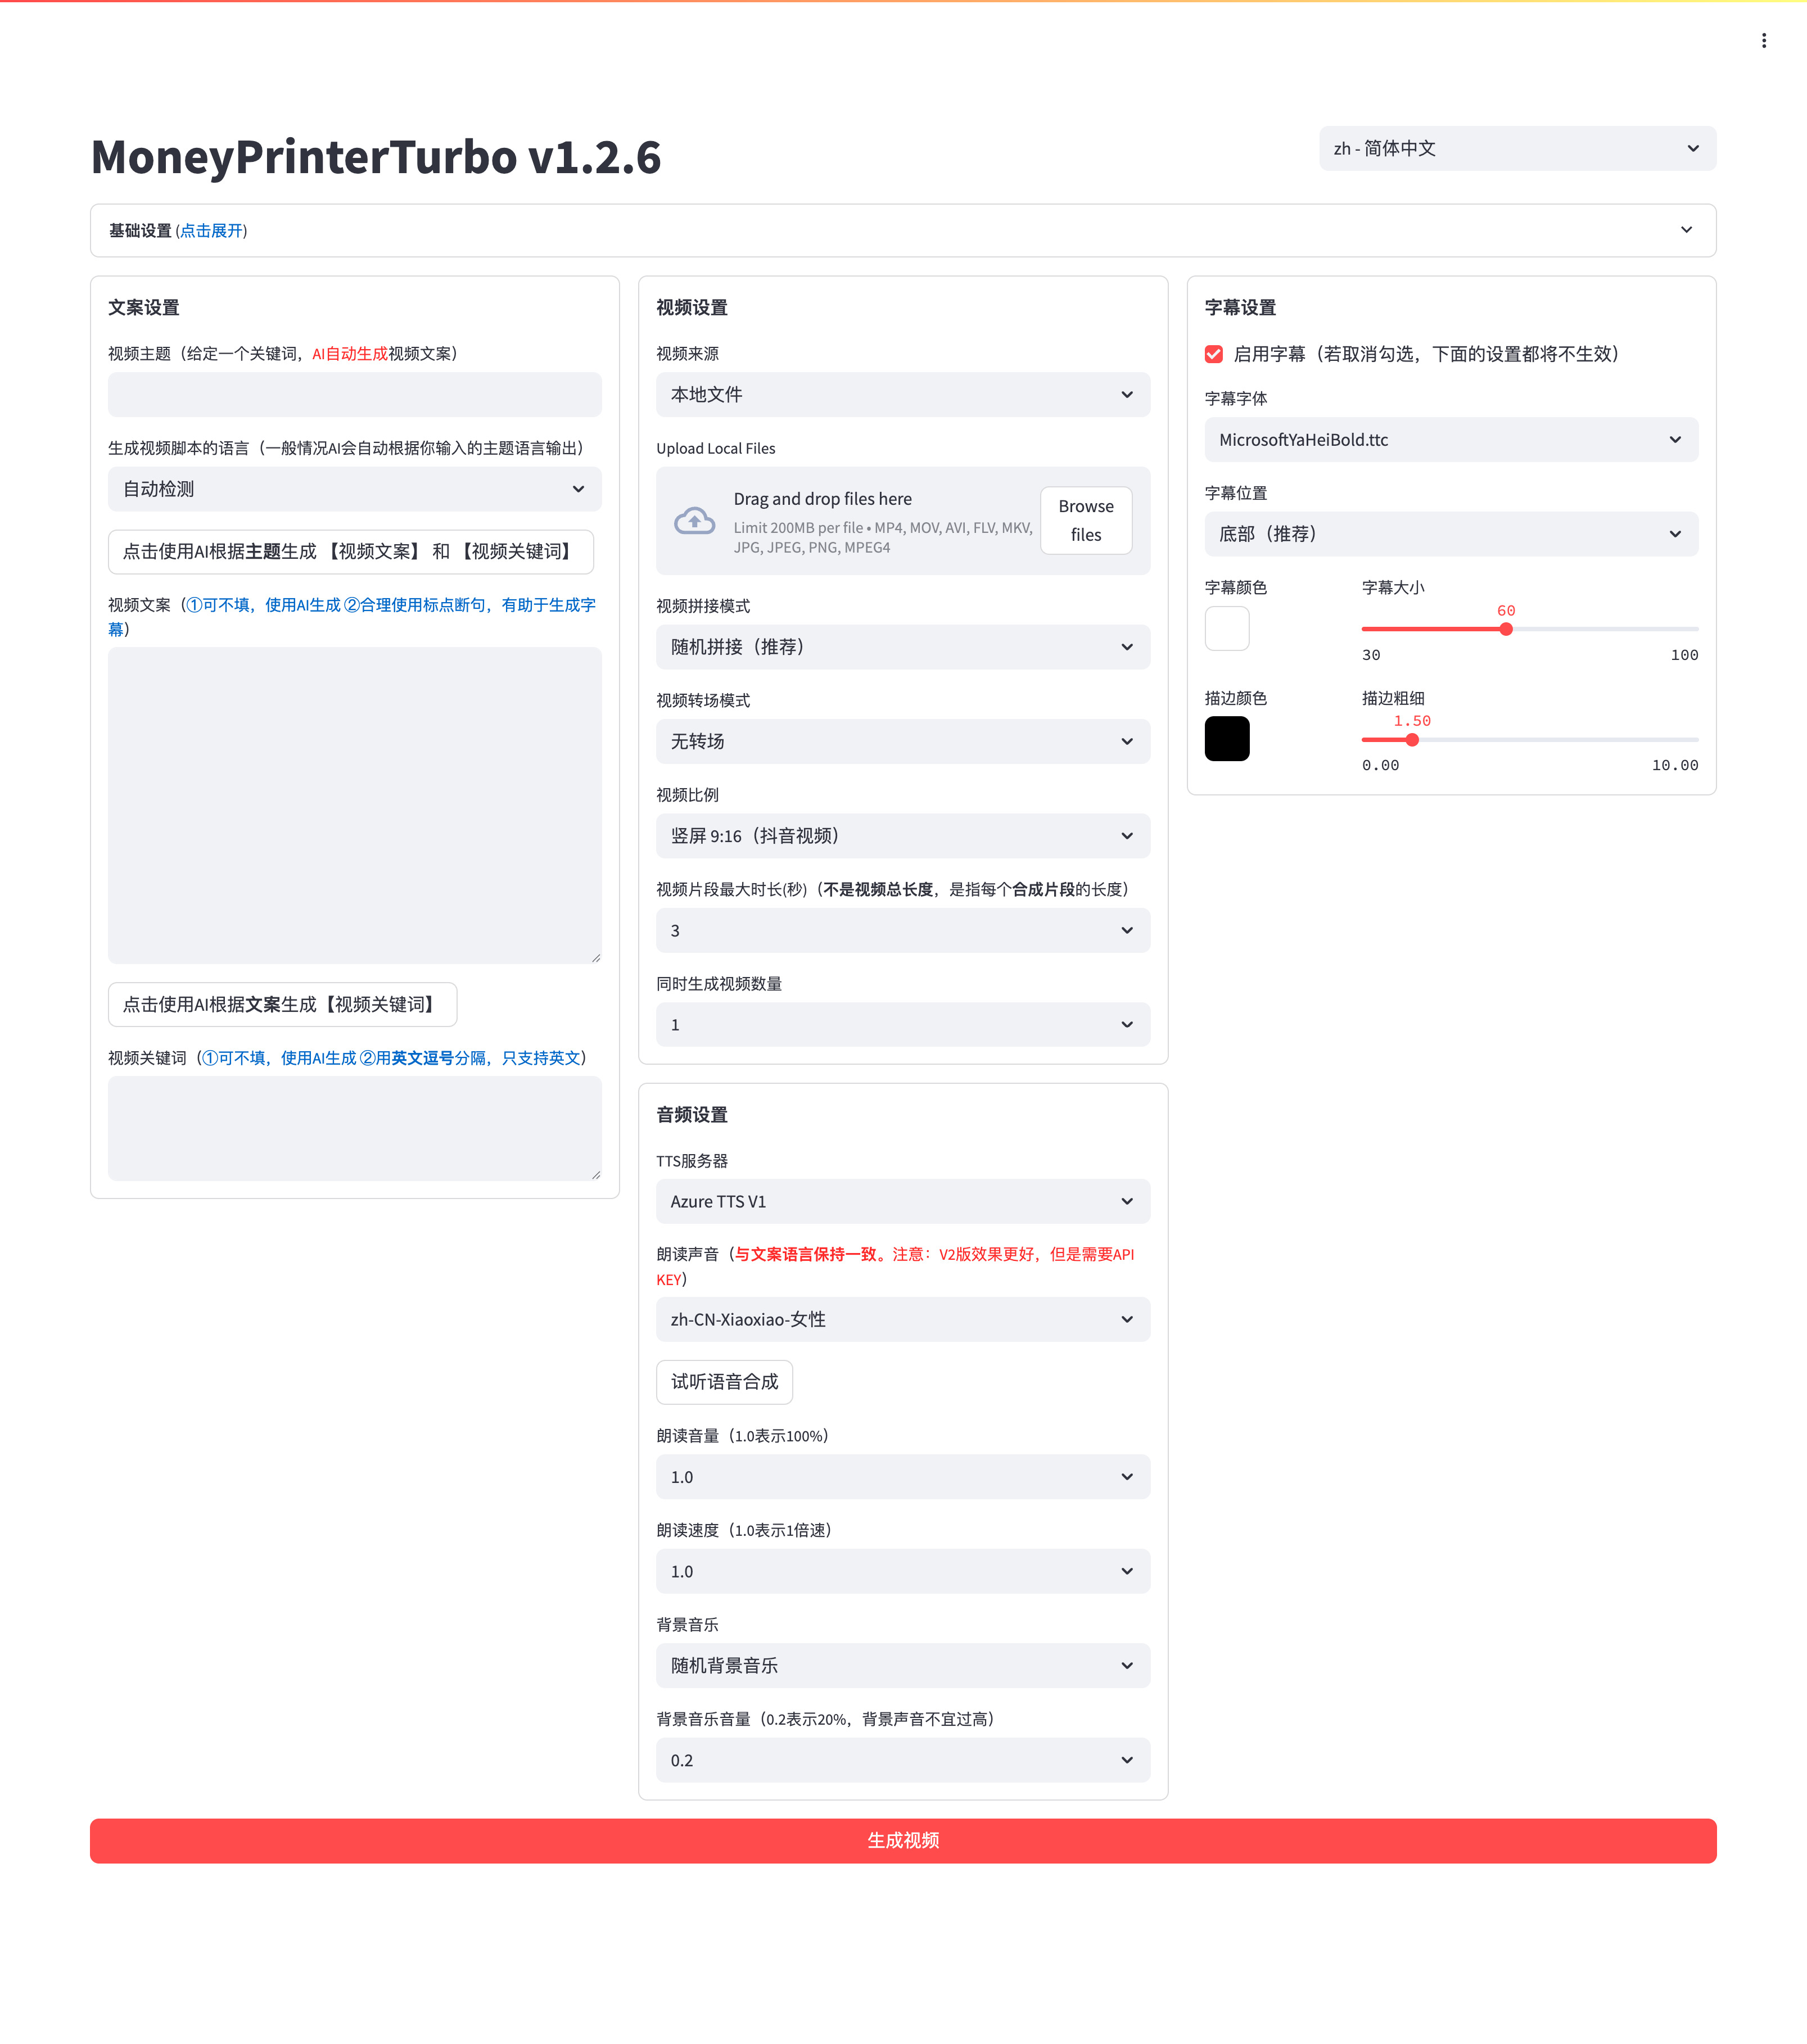
Provide a video topic or keyword, and MoneyPrinterTurbo will generate the script, match footage, create subtitles and background music, and produce an HD short video.
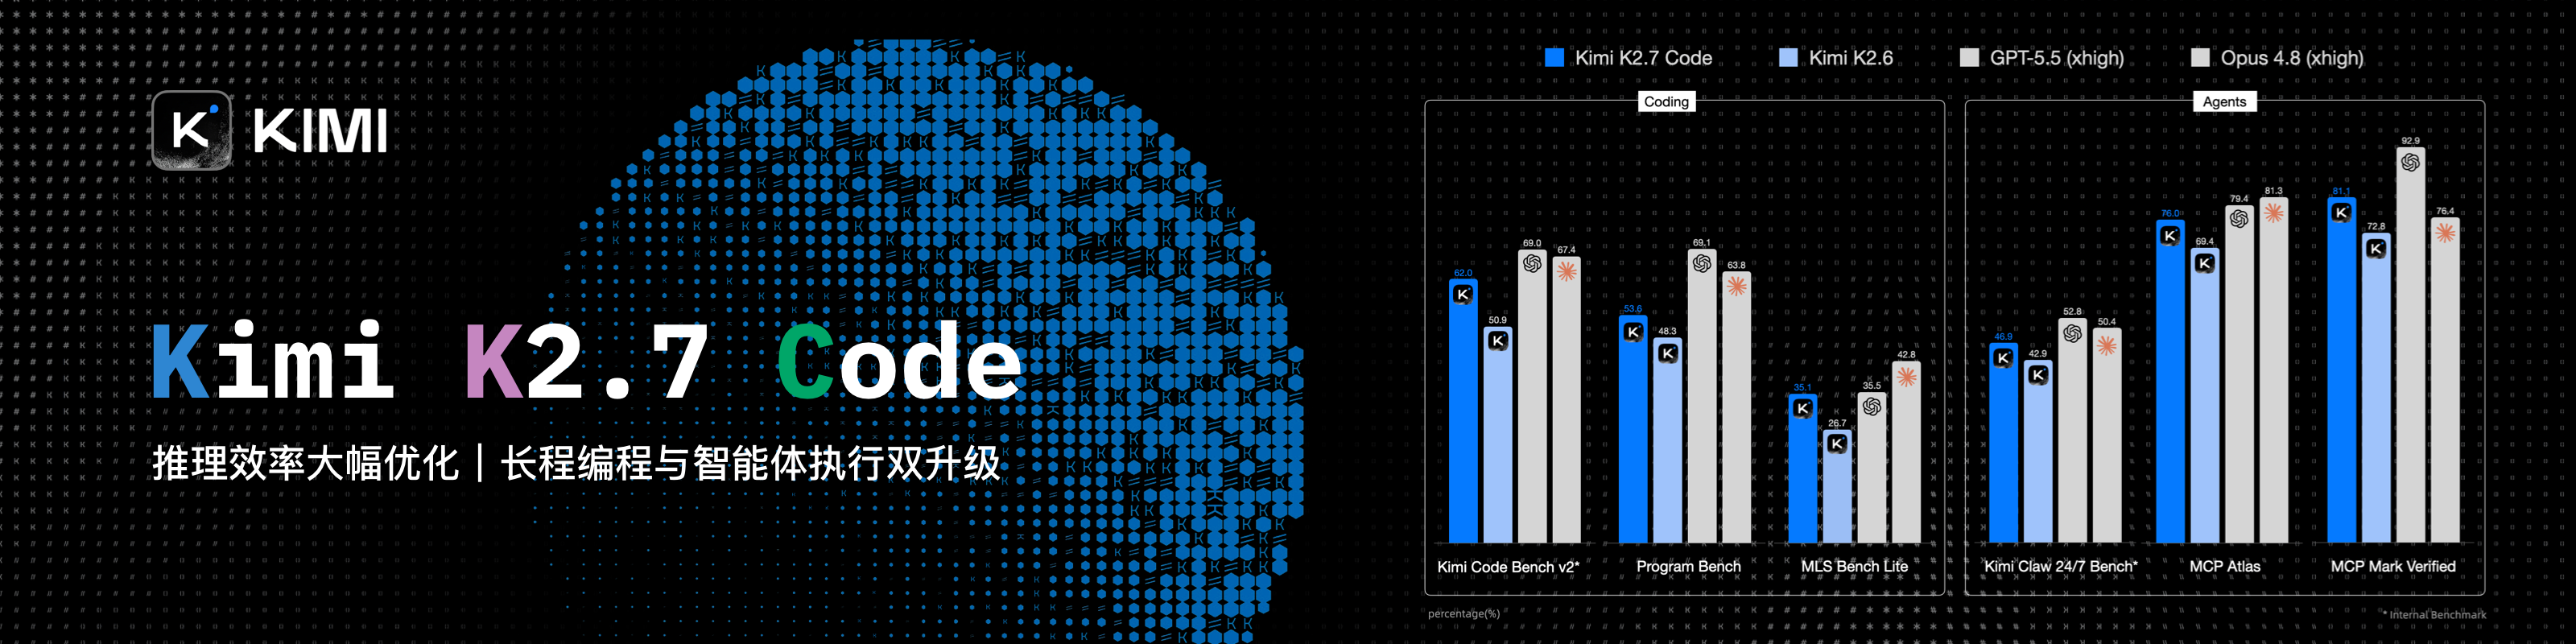
Thanks to Kimi for sponsoring this project! Kimi K3 is Moonshot AI's most capable model and the world's first open 3T-class model. With native vision and a 1-million-token context window, K3 delivers frontier performance across knowledge work, reasoning, and long-horizon tasks. Within MoneyPrinterTurbo, K3 powers video creation by writing scripts and extracting the search keywords that determine the final footage—the better it understands the content, the more relevant the results.
Exclusive offer for MoneyPrinterTurbo users: new users who register through the dedicated link receive bonus API credit equal to 10% of their first successful top-up, up to CNY 1,000. The offer ends December 31, 2026. Visit the Kimi Open Platform (中文站 | Global) to try the API.
Thanks to ByteDance VolcEngine for sponsoring this project! VolcEngine Ark's Agent/Coding Plan for leading Chinese models starts at CNY 9.9 for first-time buyers and supports GLM-5.3, Kimi-K3, DeepSeek, MiniMax, Doubao, and more. New users receive 25 million free tokens. One unified API is designed for coding and agent development. Visit now
Thanks to APIMart for sponsoring this project! APIMart is a low-cost API platform for AI image & video generation — GPT-Image-2 from $0.006/image, 160+ images per dollar. One async API covers both image and video—switch models without changing code. Submit a task, get an ID, and fetch results via polling or callback. Batch tens of thousands of images without timeouts. Pay-as-you-go with no monthly fee — sign up here to get started.
MiniMax H3 Video Generation API by Metaso
Metaso offers a cost-effective MiniMax H3 video generation service: 768p for just CNY 0.09 per second and 2K for CNY 0.15 per second. It supports native 2K output, synchronized audio and video, an OpenAI-compatible API, and ComfyUI—all without requiring you to deploy or manage GPUs.
🎁 Sign up through the exclusive MoneyPrinterTurbo link to receive bonus credits and special offers.
Thanks to Infistar.cc for sponsoring this open-source project! Infistar.cc offers cost-effective AI API access: LLMs from 1% of official rates and AI image generation from CNY 0.06 per image. One API key for text, image, and video creation, with access to leading models including GPT, Claude, Gemini, DeepSeek, Qwen, and Kling—no separate API groups required. Authenticity checks for every model, transparent pricing, an ICP filing in China, real-time billing in CNY, and business invoices available.
🎁 Exclusive MPT offer: register through our dedicated link to receive $5 in trial credits and a special first-top-up offer.
Thanks to OfoxAI for sponsoring this project! MoneyPrinterTurbo already supports Ofox multi-model text-to-video generation—just configure your API key to get started. Create video assets with Seedance, MiniMax H3, and Wan; design cover images with GPT Image 2.5 and Seedream; and refine scripts or build applications with GPT, Claude, Gemini, and DeepSeek. One key and a shared balance for text, image, and video models, with OpenAI-compatible endpoints and native Anthropic and Gemini interfaces. Pay-as-you-go billing, transparent pricing, and official model-provider channels deliver stable, high-speed, unlimited access. Explore OfoxAI models and pricing.
Thanks to Shengsuan Cloud for sponsoring this project! Shengsuan Cloud is an API aggregation platform for AI-native teams, providing unified, usage-based access to leading language and multimodal models including Claude, ChatGPT, and Gemini.
The platform focuses on compliant API services and also offers enterprise gateways with team cost and permission management, intelligent routing, security controls, BYOK credential management, and invoice support.
🎁 New users who register through this link can receive CNY 10 in trial credits.
Thanks to AstraFlow for sponsoring this project! Claim CNY 50 in compute credits.
🎬 One platform for leading video models: access MiniMax-H3, Seedance-2.5, and more. Generate scripts and videos in one place, without separate accounts or integrations.
🚀 200+ AI models, with new models available on release day: access DeepSeek V4.1, Kimi K3, Qwen 3.8 Max, GLM 5.3, and more through a single platform.
💰 Built by publicly listed UCloud, with transparent billing and cost control: track costs by API key and view detailed usage records.
🎁 Exclusive offer for MoneyPrinterTurbo users: register through our referral link to receive new-user credits and get started right away!
Thanks to Sidrune AI for sponsoring this project! One gateway to access and manage leading AI models worldwide. Built for individual developers, technical teams, and enterprises, Sidrune AI offers a unified API to access and manage leading models. It dynamically selects between multiple routes to improve availability, with transparent model performance, response times, and costs. Depending on the model and route, API costs can be 40%–98% lower than official or benchmark rates. Sign up through our exclusive link to receive $3 in API credits.
Thanks to RunningHub API for sponsoring this project!
Access 400+ leading AI models via API—including Seedance, Kling, MiniMax, Nano Banana, Veo, and more—at highly competitive prices. High-concurrency support · Free API testing · End-to-end encryption
For discounts and free testing, contact zhenyuedong@haima.me, or test the API for free.
Thanks to RecCloud, an AI-powered multimedia platform, for offering a free AI Video Generator based on this project. Use it online with no deployment required—a beginner-friendly way to get started.
Thanks to Picwish for supporting and sponsoring this project! Picwish offers a wide range of easy-to-use online image editing tools to help users handle everyday image editing tasks with ease.
Another Open-Source Project from the Creator: MangoDisk ⭐
An open-source disk cleaner, storage analyzer, and system optimizer for macOS and Windows
Clean caches, large files, duplicates, and app leftovers; analyze disk usage; manage apps and startup items; and maintain your system.
Generate 768P or 2K source footage with Metaso MiniMax H3, with 4–15 second clips in 9:16, 16:9, or 1:1
Create multiple AI video clips with Shengsuan Cloud AI Video, then combine them with the project's voiceover, subtitle, and editing workflow
Use the native Volcano Engine Ark Seedance integration to generate cohesive visuals from individual script segments
Turn script keywords into original video footage with WaveSpeed AI
Access Seedance, Wan, and other text-to-video models through OFox with a single API key
Generate 3–12 second AI video materials through the asynchronous MuAPI text-to-video API, with configurable endpoint, aspect ratio, resolution, and polling
Connect OpenAI-compatible text-to-image services or custom image gateways and turn generated images into animated video clips
Adjust clip duration, frame fitting, and material order to suit different aspect ratios and storytelling styles
Voiceover, Subtitles, and Background Music
Choose automatic voiceover, uploaded audio, or no voiceover, with voice samples and full narration previews
Use Edge TTS (free, no API key required), Azure Speech, SiliconFlow, Google Gemini, Xiaomi MiMo, MiniMax, ElevenLabs, Chatterbox, Kokoro, Fish Audio, ModelBest VoxCPM, and other voice services
Generate subtitles and configure their font, position, color, size, outline, and background style
Use random, local, or AI-generated background music with independent volume control
Publish completed videos directly to TikTok, Instagram, and YouTube Shorts
Gallery 🎬
All examples below were generated with MoneyPrinterTurbo.
Portrait 9:16
When the City Wakes Chinese · 14 sec
The Future of Clean Energy Chinese · 24 sec
Why We Still Explore Space Chinese · 27 sec
A Seed's Journey Chinese · 44 sec
The Future of Everyday Robotics English · 21 sec
Small Habits, Lasting Change English · 19 sec
Making Space for Creative Work English · 20 sec
The Science Inside Coffee English · 23 sec
Landscape 16:9
Light in the Deep Ocean Chinese · 23 sec
How Reading Shapes Us Chinese · 23 sec
The Details of Pour-Over Coffee Chinese · 23 sec
Spring Is Made for Travel Chinese · 14 sec
Why Ocean Conservation Matters English · 25 sec
Designing More Sustainable Cities English · 27 sec
What Mountains Teach Us English · 18 sec
A Brief History of Human Flight English · 59 sec
System Requirements 📦
Recommended platforms: Windows 10+, macOS 11+, or a mainstream Linux distribution
Local deployment requires Python 3.11 or later; Python 3.11 is recommended
A GPU is not required, but it is recommended if you want faster local transcription, faster video processing, or smoother batch generation
Item
Minimum
Recommended
Optimal
CPU
4 cores
6 to 8 cores
8+ cores
RAM
4 GB
8 GB
16+ GB
GPU
Not required
4+ GB VRAM
8+ GB VRAM
If you mainly rely on cloud LLMs, cloud TTS, and online material sources, CPU and RAM matter more than GPU
If you use faster-whisper, batch generation, or heavier local processing, a GPU will improve throughput noticeably
Quick Start 🚀
Recommended Paths
If you do not want to install or configure the project manually: generate videos with an AI Agent
Windows users: use the one-click package first for the fastest local trial
macOS / Linux users: use uv for the primary local setup path
If you want a more isolated runtime: use Docker deployment
Generate Videos with an AI Agent
If your AI Agent can read Skill documents and operate a local terminal, send it the prompt below. The Agent will install and configure MoneyPrinterTurbo, generate the video, and return the video file path. It will ask only for required API keys that are not already configured. This workflow currently supports macOS and Windows.
Use this Skill: https://raw.githubusercontent.com/harry0703/MoneyPrinterTurbo/main/docs/skill/SKILL.md
Create a video with the topic "How AI is changing everyday life."
Run in Google Colab
Want to try MoneyPrinterTurbo without setting up a local environment? Run it directly in Google Colab!
Windows
Download the latest Windows one-click package from GitHub Releases, then extract it directly.
Download the .7z archive from the Assets section of that page. The
auto-generated Source code (zip) / Source code (tar.gz) archives contain
source code only: after extracting them you get webui.bat but no start.bat
or update.bat.
After downloading, it is recommended to double-clickupdate.bat first to update to the latest code, then double-click start.bat to launch
After launching, the browser will open automatically (if it opens blank, it is recommended to use Chrome or Edge)
macOS / Linux
Use the local setup or Docker instructions below.
Installation & Deployment 📥
Prerequisites
Local deployment requires Python 3.11 or later
On Windows, avoid project paths containing non-ASCII characters, special characters, or spaces
On first launch, the project creates config.toml from config.example.toml, so you do not need to create the file manually. Before using cloud LLMs, online footage, or AI video services, add the corresponding API keys in the WebUI basic settings.
Docker Deployment 🐳
① Launch the Docker Container
If Docker is not installed, download and install Docker Desktop first.
If you are using a Windows system, please refer to Microsoft's documentation:
cd MoneyPrinterTurbo
docker compose -f docker-compose.release.yml up
The recommended default is docker-compose.release.yml, which pulls the prebuilt image from GitHub Container Registry: ghcr.io/harry0703/moneyprinterturbo:latest.
If you need to build the image locally, you can still run docker compose up.
Before the first start, copy config.example.toml to config.toml so it can be mounted into the containers.
The API allows same-origin browser access by default. Set the CORS_ALLOWED_ORIGINS environment variable only when a separate browser frontend must call the API directly from another origin, for example http://localhost:3000,https://frontend.example.com. CORS does not affect curl, Postman, n8n, or other server-side clients.
Manual Deployment 📦
① Create a Python Virtual Environment
Use uv to manage the Python environment and dependencies. The project supports Python 3.11 or later; the example below uses Python 3.11.
pyproject.toml is now the primary dependency manifest.
uv.lock pins the resolved environment, so uv sync --frozen is recommended by default.
requirements.txt is kept only for legacy pip-based installation.
② Launch the WebUI 🌐
Note that you need to execute the following commands in the root directory of the MoneyPrinterTurbo project
Windows
.\webui.bat
You can also run webui.bat in CMD.
webui.bat prefers the project .venv or bundled Python from the portable package. If no project Python is found but uv is installed, it automatically falls back to uv run streamlit.
To allow other devices on your LAN to access the WebUI, run set MPT_WEBUI_HOST=0.0.0.0 before running webui.bat.
macOS or Linux
sh webui.sh
The script automatically uses the project virtual environment or uv and selects an available local port. To allow access from other devices on your LAN, run:
MPT_WEBUI_HOST=0.0.0.0 sh webui.sh
After launching, the browser will open automatically
③ Launch the API Service 🚀
uv run python main.py
If you have already activated the virtual environment manually, you can still run:
python main.py
④ Pure CLI Mode (No Browser) ⌨️
If you cannot use a browser or port forwarding, generate videos directly from the
command line. The simplest complete generation command is:
uv run python cli.py --video-subject "How AI is changing everyday life"
Subtitle style and voiceover options resolve in this order: explicit CLI option >
saved [ui] value in config.toml > built-in default. Other generation settings,
such as background music, video count, and paragraph count, are not inherited from
the WebUI. If the WebUI is set to use uploaded audio, pass --custom-audio-file
explicitly, since the uploaded path is not persisted.
For the complete command reference, parameter descriptions, and usage instructions,
run:
uv run python cli.py --help
To run several tasks sequentially, pass a UTF-8 JSON array or JSONL manifest. CLI
options act as defaults, and each object overrides fields from VideoParams:
uv run python cli.py --batch-file ./tasks.json --stop-at video
The manifest is resolved from the current working directory. Relative
custom_audio_file and local video_materials[].url values inside it are resolved
from the manifest's directory; file paths supplied as CLI defaults keep their normal
current-working-directory semantics. A manifest is limited to 100 tasks and 1 MiB.
All entries are validated before the first task starts, tasks continue after an
individual runtime failure, and the command prints one JSON summary when finished.
The summary contains total, succeeded, failed, and tasks; each task entry has
index, task_id, status, result, failed_stage, and error.
Voiceover, Subtitles, and Background Music 🎙️
Voice Synthesis
ElevenLabs speech speed depends on the selected model. The default eleven_multilingual_v2 accepts 0.7×–1.2×; select eleven_v3 for the wider 0.25×–4.0× REST range. MoneyPrinterTurbo reports unsupported selections before sending a generation request and preserves the selected rate without clamping. Non-default speeds on eleven_v4/eleven_v4_turbo are unsupported. Other model IDs use a conservative 0.7×–1.2× validation range; this does not guarantee that every model supports the speed setting. If the provider returns invalid_voice_settings, generation stops without retrying and shows its explanation. The live v2/v3 validation reported by the maintainer takes precedence over the broader range described in the official voice-settings reference.
Azure TTS V1 in the WebUI is powered by Edge TTS and is free to use without an API key. MoneyPrinterTurbo also supports Azure TTS V2, SiliconFlow TTS, Google Gemini TTS, Xiaomi MiMo TTS, MiniMax TTS, ElevenLabs TTS, self-hosted Chatterbox TTS, self-hosted Kokoro TTS, Fish Audio TTS, ModelBest VoxCPM TTS, and a no-voice mode.
Select a provider and voice in the WebUI, then follow the on-screen instructions for any required credentials. Edge TTS does not require an API key; Azure TTS V2 and other cloud providers require credentials from their respective platforms. See the available Edge TTS voices in the voice list.
ModelBest VoxCPM requires an API key and a model ID with the speech_synthesis capability. Its SSE response streams WAV audio, which MoneyPrinterTurbo automatically converts to the MP3 used by the video pipeline. In addition to standard text-to-speech, the WebUI can clone speaker identity from optional reference audio. High-fidelity delivery reuses that clip with its exact transcript by default, or accepts a separate performance example, and sends prompt_audio plus prompt_text to continue its pacing, emotion, and pronunciation. The WebUI can use the local Whisper configuration to create an editable transcript draft. Uploads are limited to 20 MiB and each converted WAV to 5 MiB. Reference material is scoped to the current browser session and task and is not written to configuration, presets, task history, or logs.
Subtitle Generation
Two subtitle generation modes are available:
edge: Uses TTS timestamps, runs quickly without a GPU, and is the default mode.
whisper: Uses local faster-whisper transcription when a more accurate subtitle timeline is needed. The model is downloaded on first use.
Set subtitle_provider in config.toml to switch modes. Whisper uses the approximately 3 GB large-v3 model by default. To use the smaller and faster, approximately 1.6 GB large-v3-turbo model:
On first use, Whisper automatically downloads the model from Hugging Face. If the automatic download fails, download whisper-large-v3 manually from Hugging Face.
After extracting the model, place the entire directory in .\MoneyPrinterTurbo\models. The final path should be .\MoneyPrinterTurbo\models\whisper-large-v3:
Background music for videos is located in the project's resource/songs directory.
The current project includes some default music from YouTube videos. If there are copyright issues, please delete
them.
Subtitle Fonts
Fonts for rendering video subtitles are located in the project's resource/fonts directory, and you can also add your
own fonts.
Common Questions 🤔
RuntimeError: No ffmpeg exe could be found
Normally, ffmpeg will be automatically downloaded and detected.
However, if your environment has issues preventing automatic downloads, you may encounter the following error:
RuntimeError: No ffmpeg exe could be found.
Install ffmpeg on your system, or set the IMAGEIO_FFMPEG_EXE environment variable.
In this case, download FFmpeg from gyan.dev, extract it, and set ffmpeg_path to
the actual installation path.
[app]
# Please set according to your actual path, note that Windows path separators are \\
ffmpeg_path = "C:\\Users\\harry\\Downloads\\ffmpeg.exe"
OSError: [Errno 24] Too many open files
This issue is caused by the system's limit on the number of open files. You can solve it by modifying the system's file open limit.
Check the current limit:
ulimit -n
If it's too low, you can increase it, for example:
ulimit -n 10240
Whisper model download failed
LocalEntryNotFoundError: Cannot find an appropriate cached snapshot folder for the specified revision on the local disk and
outgoing traffic has been disabled.
To enable repo look-ups and downloads online, pass 'local_files_only=False' as input.
or
An error occurred while synchronizing the model Systran/faster-whisper-large-v3 from the Hugging Face Hub:
An error happened while trying to locate the files on the Hub and we cannot find the appropriate snapshot folder for the
specified revision on the local disk. Please check your internet connection and try again.
Trying to load the model directly from the local cache, if it exists.
Use revision-aware local projects to replace prepared scene media, compare revisions and rebuild only affected stages. The opt-in CLI preserves verified artifacts and the last successful export; it makes no provider calls or automatic posts.